🎬 Behind the Scenes of Lively Out Loud Episode #5: How We Brought This Podcast to Life
Good content doesn’t just speak — it shines. And if you’ve seen Lively Out Loud Episode #5, you already know: this one shines.
But here’s the thing most people don’t realise — what you see on screen (and what makes you want to click in the first place) doesn’t happen by accident. It’s the result of sharp editing, smart visual choices, and a thumbnail that demands attention.
In this post, we’re pulling back the curtain on what we did behind the scenes to help shape Episode #5 into the polished, engaging, and scroll-stopping piece of content it became.
If you're a podcast host, YouTuber, or content creator, this is what great support looks like — and it’s exactly what we can do for your next project.
🎧 The Brief: Turn Raw Podcast Footage into a Polished Episode
The Lively Out Loud team came to us with a clear mission:
Take the recorded footage from Episode #5 — a vibrant, unscripted conversation between two brilliant women — and transform it into a clean, engaging, ready-to-publish episode for YouTube.
They wanted:
- ✂️ Tight, clean editing that kept the flow natural
- 🔊 Balanced audio with crisp vocal clarity
- 🎨 A scroll-stopping thumbnail that captured the vibe of the episode
- 📺 A final product that looked and felt professional, not DIY
🎞️ Our Video Editing Process
Step 1: Clean the Cut
We started by trimming out the unnecessary bits — pauses, stumbles, tech glitches — while preserving the natural energy of the conversation. No robotic jump cuts. Just smooth, invisible edits that help the episode breathe.
Step 2: Sound Polish
Audio matters. We levelled the voices, cleaned background noise, and added subtle EQ to make sure it sounds as good as it looks. Good sound = longer watch time.
Step 3: Story-Driven Pacing
Editing isn't just about cutting — it's about shaping the story. We used pacing techniques to let emotional beats land, highlight key moments, and keep viewers engaged.
🖼️ The Thumbnail: Designed to Be Clicked
A great thumbnail isn’t just a picture. It’s a promise.
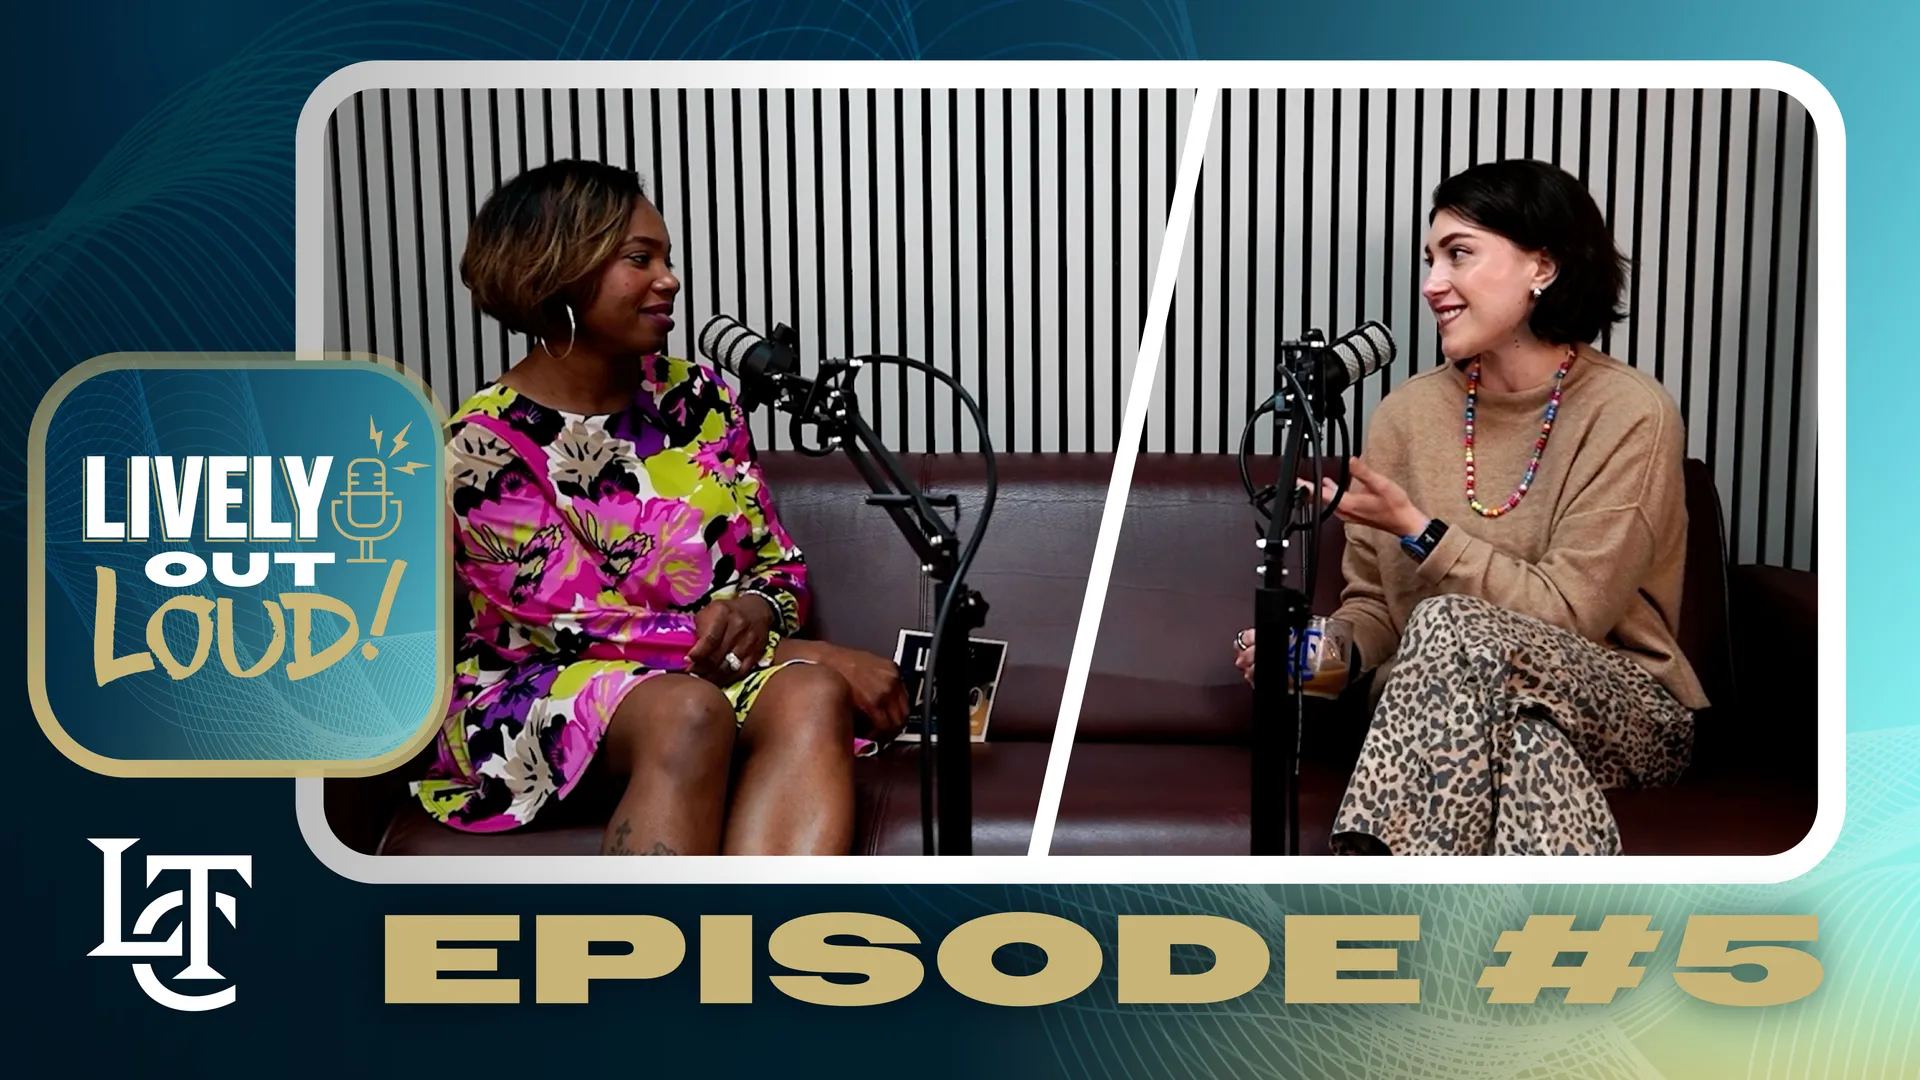
For Episode #5, we created a bold, colourful visual that instantly told the viewer what to expect: a lively, face-to-face conversation between two powerful women — full of personality and style.
Here's what we focused on:
- Contrast + Colour: Bright tones to stand out on the YouTube feed
- Split-Screen Style: Highlights both speakers equally
- On-Brand Typography: Consistent with the Lively Out Loud identity
- Clear Episode Numbering: Helps build audience continuity
The result? A visual that catches the eye, sparks curiosity, and aligns perfectly with the vibe of the show.
🧠 Small Choices That Made a Big Impact
Sometimes it’s the subtle details that elevate a project:
- We chose a clean cut style to keep the focus on the chemistry between the guests.
- We timed transitions with natural laughter and beats in the dialogue.
- We matched colour tones in the thumbnail to the set, creating visual harmony.
It’s this kind of attention to detail that separates “content” from content that connects.
🚀 Want This for Your Podcast or YouTube Channel?
If you're tired of DIY editing, half-baked thumbnails, or content that doesn't quite land — we’re here to help.
We offer:
- Full video editing for podcasts, interviews, and YouTube content
- Thumbnail design that’s built to stop the scroll
- End-to-end support so you can focus on your voice, not your timeline
📩 Get in touch to chat about your next project.
Whether you’re just starting out or levelling up your show, we’ll help you look as professional as you sound.
Lively Out Loud Episode #5 wasn’t just a great episode — it was a team effort.
And if you want your next project to stand out just like this one did, you know where to find us.
Have something to build?
Design and engineering under one roof — we scope it, build it, and stay for the long tail.
Start a projectKeep ReadingMore case studies like this
Engineering retros, product launches, and brand systems from our studio — updated monthly.
All case studiesTechnology Used
 Adobe After Effects
 Adobe Premiere Pro
 Adobe Audition
Tags & Keywords
Continue with Blogs.
View all blogs Dedicated Development Team
What Does It Cost to Hire a Dedicated Development Team? (2026)
Short answer: a dedicated development team costs between $10,000 and $200,000+ per month in 2026. The spread comes down to two things: where your engineers sit and how many of them you need. A small MVP team of 3–4 people runs roughly $9,000–$26,000 a month offshore (India, Ukraine, Poland) and $30,000–$45,000 in the US. That range is wide enough to be useless on its own. So below you'll find the actual hourly rates by region and role, three real team configurations priced out, the hidden costs that quietly add 20–30% to most quotes, and a simple formula to calculate your own budget before you talk to a single vendor. We run a dedicated-team practice at Craxinno , a Jaipur-based studio that has been building software since 2017. We'll show you our own pricing too, so you have one number in the market that isn't hidden behind a "contact us" button. Dedicated Development Team Cost at a Glance (2026) Here's the monthly cost of one full-time engineer (about 160 billable hours) by region. These figures come from 2026 market surveys published by outsourcing vendors including N-iX/Ncube and Integrio . Region Hourly rate Monthly cost per developer North America $100–$175 $16,000–$28,000 Western Europe $75–$120 $12,000–$20,000 Eastern Europe $45–$80 $7,500–$13,000 Latin America $35–$65 $6,000–$11,000 South & Southeast Asia (India, Vietnam) $25–$50 $4,000–$8,500 Notice the gap. A senior engineer in San Francisco and a senior engineer in Jaipur can ship the same React app. One costs you roughly four times more per month. That's the whole reason the dedicated team model exists. What Is a Dedicated Development Team, Exactly? A dedicated development team is a group of engineers, designers, and QA specialists hired through a vendor who work only on your product, full-time, for months or years. You direct the work. The vendor handles hiring, payroll, office, equipment, HR, and replacements. Here's how it compares with the other ways to hire: Fixed-price project: you agree on a scope and a price up front. Good for a defined MVP . Painful when requirements change (and they always change). Staff augmentation: you rent one or two engineers to plug gaps in your existing team. Dedicated team: you get a full, stable unit (developers, QA, often a PM) that behaves like your own in-house department. In-house hiring: you recruit and employ everyone yourself , with salaries, benefits, recruiting fees, and months of hiring time. If your product will need continuous development for six months or longer, the dedicated model is usually the cheapest way to get a team that actually knows your codebase. Hourly Rates by Role (2026) Not every seat costs the same. A DevOps engineer is priced very differently from a junior front-end developer. Here are typical 2026 hourly rates across the three most popular outsourcing regions: Role Asia Latin America Eastern Europe Junior developer $12–$22 $15–$25 $20–$35 Mid-level developer $22–$38 $30–$50 $40–$65 Senior developer $38–$60 $55–$80 $65–$100 QA engineer $15–$30 $20–$40 $25–$55 DevOps engineer $30–$55 $45–$75 $55–$90 Project manager $25–$45 $35–$60 $45–$75 One practical tip: you rarely need an all-senior team. A ratio of roughly one senior to two mid-level developers keeps code quality high and can bring your blended rate down by as much as 20%. The senior reviews, the mid-levels build. It works. How Much Does a Dedicated Team Cost Per Month? 3 Real Configurations Rates are abstract. Teams are what you actually pay for. Here's how the monthly bill looks for three common setups. 1. Small MVP team (3–4 people) Who's on it: 2–3 developers (say, one React and one Node.js), a QA engineer (often part-time), and a part-time PM. Region Monthly cost USA $30,000–$45,000 Eastern Europe (Poland, Ukraine) $9,000–$18,000 Asia (India) $10,000–$26,000 This is the team for getting a first version in front of users in 3–4 months. You'll want your own product owner or tech lead making decisions; the team executes. 2. Mid-size SaaS team (6–9 people) Who's on it: a PM, a business analyst, 2 front-end developers, 1–2 back-end developers, a UI/UX designer, manual and automation QA, and a DevOps engineer. Region Monthly cost USA $80,000–$120,000 Canada $65,000–$95,000 Poland $35,000–$50,000 Asia $24,000–$56,000 At this size you're running a real product : weekly releases, a proper CI/CD pipeline, and someone whose whole job is making sure nothing breaks in production. 3. Enterprise team (10+ people) Who's on it: a tech lead or architect, PM, BA, 5–6 developers across stacks, UI/UX, 2 automation QA, DevOps, and a cloud engineer. Often split into pods per product area. Region Monthly cost USA $150,000–$220,000 Eastern Europe $45,000–$95,000 Asia $55,000–$120,000+ What We Charge at Craxinno (Real Numbers) Most agency articles on this topic end with "contact us for a quote." We'd rather just tell you. Craxinno bills dedicated engineers at $25 per hour . At a standard 160-hour month, that's $4,000 per full-time team member . So: 2 developers (starter pod): about $8,000/month 3 developers + 1 QA (MVP team): about $16,000/month 5 developers + QA + designer (growth team): about $28,000/month Same rate across web, mobile, AI/GenAI, and cloud work . No AI premium, no separate line for the account manager. If you're comparing quotes, put this number next to the others and ask each vendor what's included. That question alone tells you a lot. What Drives the Cost Up (or Down)? Location is the biggest lever. It isn't the only one. Tech stack. Common stacks like React, Node.js, Laravel, or Python/Django have deep talent pools and stable rates. Niche skills (Rust, blockchain, computer vision, LLM fine-tuning) cost more because fewer people can do them well. Some vendors add a 20–30% premium for AI/ML pods . Seniority mix. Covered above. An all-senior team is a luxury most products don't need. Engagement length. Commit to 6–12 months and many vendors drop their monthly rate by 10–15%. Month-to-month flexibility costs extra. Who leads. A vendor that provides a CTO-level architect who makes technical decisions charges 15–25% more than an execution-only team. Worth it if you don't have a technical co-founder. Wasted money if you do. Time-zone overlap. Want your offshore team online for your entire US workday? Expect to pay for night-shift coverage. A 3–4 hour overlap window is usually enough, and it's free. The Hidden Costs Most Founders Miss You get a quote of $16,000/month. You budget $16,000/month. Three months later you've spent closer to $20,000 a month and you're not sure where it went. A safe rule: add 20–30% to any quote to cover these. Ramp-up time. Expect 2–4 weeks at full cost before the team hits full speed. They're reading your code and learning your domain. Your own management time. Someone on your side (founder, PM, or tech lead) will spend 3–8 hours a week on reviews, priorities, and answering questions. That time isn't free. Tooling and infrastructure. Jira, GitHub seats, Figma, staging servers, AWS bills, monitoring. These add up on long projects. Roles billed separately. Some vendors quote developer rates only , then add QA, DevOps, and PM on top. A vendor PM alone can add $2,000–$5,000/month. Get it in writing. Replacement fees. If an engineer leaves, some vendors charge to replace them. Good ones don't. Legal and compliance. Contract review, NDAs, IP assignment, and security audits if you're in healthcare, fintech, or another regulated space. Dedicated Team vs. In-House Hiring: The Real Comparison A senior software engineer in the US commonly earns well into six figures. Then add benefits, payroll taxes, equipment, office space, and a recruiter fee that's often 15–25% of first-year salary. And you'll wait 2–3 months to fill each seat. A dedicated team skips most of that. No recruiting fees, no benefits, no severance. You can usually start within 1–3 weeks and scale up or down with a month's notice. The trade-off is control and context. Your in-house engineers sit in your Slack all day and absorb the business. A dedicated team needs clear documentation, regular calls, and a single point of contact on your side. Give them that and the gap closes fast. Factor In-house team Dedicated team Freelancers Time to start 2–4 months 1–3 weeks Days Hiring & HR overhead You Vendor You Scaling up/down Slow, costly ~1 month notice Fast, unstable Long-term product knowledge High High Low Replacement if someone leaves You re-hire Vendor replaces Start over How to Calculate Your Dedicated Team Budget Use this formula before you request any quotes: Monthly budget = (number of team members × hourly rate × 160) × 1.25 The 1.25 covers the hidden costs above. Example: a team of 4 at $25/hour = 4 × 25 × 160 = $16,000, times 1.25 = $20,000/month all-in . Multiply by your expected timeline ( an MVP usually takes 3–6 months ) and you have a real number to take to your board, your co-founder, or your bank. Then work backwards: Define the first milestone. Not the full product. Just the first version real users can touch . List the roles that milestone needs. A mobile app needs a mobile developer. A data dashboard needs a back-end developer who's comfortable with SQL. Don't hire roles you won't use for 3 months. Pick your region based on budget, time-zone needs, and language. Run the formula. If the number's too high, cut scope before you cut seniority. How to Reduce Costs Without Hurting Quality Start smaller than you think. Two good engineers for the first month will tell you more about the vendor than any sales call. Use a blended seniority mix. One senior for every two mid-level developers. Sign a longer commitment once the trial month goes well, to unlock a 10–15% discount. Write things down. Clear tickets and a short product spec cut ramp-up time in half. Vague tickets are the most expensive thing in outsourcing. Own the repo and cloud accounts from day one. It costs nothing and saves you a painful handover later. Red Flags When Choosing a Dedicated Team Provider They won't share hourly rates until after three calls. You can't interview the actual engineers who'll work on your project. The contract doesn't clearly assign IP and source code to you. There's no trial period or a very long notice period to exit. They quote a fixed "team price" but won't say which roles it includes. Every portfolio project looks like a template . The single best question to ask any vendor: "Who reviews the code and makes architecture decisions on my project?" If the answer is vague, the price doesn't matter . So, What Should You Budget? If you're a startup building an MVP, plan for $9,000–$26,000 a month with an offshore team in India, Southeast Asia, or Eastern Europe. If you're scaling an existing SaaS product , plan for $25,000–$60,000 offshore. And if you're hiring in the US, multiply those numbers by three or four. Want an exact figure for your project? Talk to the Craxinno team . Tell us what you're building and we'll send you a team plan with roles, timeline, and a monthly cost based on our $25/hour rate. You can also browse more guides on our blog .
 Next.js
Headless CMS vs Traditional CMS: Which Is Right for You? (2026)
Quick answer: Choose a traditional CMS (like WordPress, Wix or Shopify) if you need a marketing site or store live fast, on a modest budget, managed by non-technical editors. Choose a headless CMS (like Sanity, Contentful, Strapi or Storyblok) if you publish the same content to several channels — website, mobile app, kiosks, AI assistants — need top-tier performance, or want full control over the front end with a developer team to support it. If you're somewhere in between, a hybrid setup (such as headless WordPress with a Next.js front end) often gives you the best of both. The rest of this guide explains the trade-offs in plain terms, shows real 2026 numbers, and ends with a five-question test you can use to make the call in minutes. What is a traditional CMS? A traditional (or "monolithic" / "coupled") CMS keeps everything in one system: the database where content lives, the admin panel where editors write, and the theme that renders pages for visitors. You write a post, pick a template, press publish — and the CMS builds the page. WordPress, Drupal, Joomla, Wix, Squarespace and Shopify all work this way by default. Traditional CMSs still run a huge share of the web. According to W3Techs (October 2026), WordPress powers about 39.5% of all websites and 58.3% of sites using a known CMS , followed by Shopify (5.3%) and Wix (4.2%). That popularity matters: it means a large talent pool, thousands of themes and plugins, and answers to almost any problem a quick search away. Strengths Fast to launch — themes and page builders get a site live in days. Editor-friendly — what you see in the editor is close to what visitors see. Low starting cost — cheap hosting and free or low-cost plugins. Huge ecosystem — SEO, forms, e-commerce and analytics plugins out of the box. Weaknesses Front end and back end are tied together, so big design changes often mean fighting the theme. Plugin sprawl slows sites and adds risk. Patchstack's State of WordPress Security report counted roughly 8,000 new vulnerabilities in the WordPress ecosystem in 2024, with the vast majority in plugins , not WordPress core ( SecurityWeek coverage ). Content is shaped around pages , which makes reusing it in an app, a smartwatch or an AI chatbot awkward. What is a headless CMS? A headless CMS removes the "head" — the presentation layer. It stores and organises content, then serves it through an API (REST or GraphQL). Developers build the front end separately, usually with frameworks like React or Next.js , and pull content from the API. Think of it like a restaurant kitchen that no longer has its own dining room. The kitchen (your content) can now deliver to a website, a mobile app, a digital signboard and a voice assistant — all from one source. Popular options in 2026 include Sanity, Contentful, Strapi, Storyblok, Payload and Hygraph. Strengths Omnichannel by design — write once, publish everywhere. Front-end freedom — use any framework and design without theme limits. Performance — static generation, edge caching and modern frameworks make very fast pages achievable. Smaller attack surface — the public site doesn't expose an admin panel or plugin layer. Structured content — clean, typed fields that are easy to feed into search, personalisation and AI tools. Weaknesses Needs developers to build and maintain the front end. Higher upfront cost and longer build time. Editors can lose live visual preview unless the team sets it up (most leading platforms now offer visual editing, but it takes configuration). More moving parts — hosting, API, front end and build pipeline to manage. Headless vs traditional CMS: side-by-side comparison Factor Traditional CMS Headless CMS Architecture Content + presentation in one system Content backend only; front end built separately via API Time to launch Days to a few weeks Several weeks to months Upfront cost Low Medium to high Editor experience Visual, familiar, WYSIWYG Form-based by default; visual editing needs setup Design flexibility Limited by theme/builder Unlimited Performance Good with tuning; plugin bloat is common Excellent potential with static/edge delivery Security Larger attack surface (plugins, admin exposed) Smaller public attack surface Multi-channel delivery Difficult Built in Scalability Needs caching and hosting upgrades Scales well via CDN and decoupled services SEO Easy via plugins Excellent, but developers must implement meta, sitemaps, schema Developer dependency Low High Best for Blogs, brochure sites, small stores Products, apps, multi-brand, high-traffic platforms Is a headless CMS better for SEO? Not automatically. A headless CMS gives you the potential for better SEO because you control every line of HTML and can ship very fast pages — and page experience and Core Web Vitals do matter. But a traditional CMS gives you SEO basics for free : plugins handle meta titles, XML sitemaps, canonical tags, redirects and schema markup. In a headless build, developers must build each of these. Teams that skip this step often launch a beautiful, fast site that ranks worse than the old WordPress one. Rule of thumb: headless wins on SEO when your team implements server-side rendering or static generation, plus metadata, sitemaps, structured data and redirects from day one. If no one owns that work, stay traditional. What does each option really cost in 2026? Exact numbers depend on scope, but here's how the costs are shaped differently: Traditional CMS Build: theme customisation and plugin setup — lowest upfront cost. Running costs: hosting, premium plugins/themes, and regular updates. Hidden cost: plugin maintenance, security patching and performance clean-ups as the site grows. Headless CMS Build: content modelling, a custom front end and integrations — higher upfront cost. Running costs: CMS subscription (many have free tiers; paid plans rise with users, locales and API usage), front-end hosting (e.g. Vercel, Netlify or AWS) and developer time. Hidden cost: every new page type or feature usually needs developer work. The honest takeaway: a traditional CMS is cheaper to start . A headless CMS can be cheaper to scale when you're serving multiple channels or high traffic, because you avoid rebuilding content for each platform. When should you choose a traditional CMS? Pick a traditional CMS if most of these sound like you: You need a website live in weeks, not months. Your content team is non-technical and wants to publish without help. You only publish to one website. Your budget is limited and you don't have in-house developers. You need a standard blog, company site, portfolio or small online store. Example: A local clinic, restaurant or consultancy that needs a fast, good-looking site with a blog and contact form. WordPress or Wix will do the job well at a fraction of the cost. When should you choose a headless CMS? Pick a headless CMS if most of these sound like you: You publish to a website and a mobile app (or more channels). You run multiple brands, regions or languages from one content hub. Performance and design control are business-critical — for example, high-traffic marketing or e-commerce. You have (or can hire) developers comfortable with React, Next.js or similar. You want to feed structured content into search, personalisation or AI assistants. Example: A SaaS company with a marketing site, docs, in-app help and a mobile app — all pulling the same product content from one headless CMS so every channel stays in sync. The middle path: hybrid and headless WordPress You don't have to pick an extreme. Two popular in-between options: Headless WordPress — keep WordPress as the editing backend your team already knows, and build the front end in Next.js using the WordPress REST API or WPGraphQL. You keep the familiar editor and gain speed and design freedom. Hybrid CMS — platforms that offer both a traditional page-building experience and content APIs, so marketers get visual editing while developers get API access. This is often the smartest route for businesses already invested in WordPress who want a faster, more modern front end without retraining their editors. The 5-question test: which CMS is right for you? Answer yes or no: Will your content appear on more than one channel (site, app, kiosk, AI assistant) in the next 12–24 months? Do you have, or plan to hire, front-end developers ? Is page speed or custom design a direct revenue driver for you? Do you manage multiple brands, regions or languages ? Is your budget and timeline flexible enough for a longer build? 0–1 yes → Traditional CMS. Speed and simplicity win. 2–3 yes → Hybrid / headless WordPress. Keep your editors happy and modernise the front end. 4–5 yes → Headless CMS. You'll grow into its flexibility. Thinking about migrating? A quick checklist Moving from a traditional to a headless CMS is where many projects lose traffic. Protect yourself: Audit content first — remove what's outdated before you migrate it. Design the content model — turn pages into reusable fields and content types. Map every URL and set up 301 redirects for any that change. Rebuild SEO essentials — metadata, sitemaps, canonicals and schema. Set up previews so editors can see changes before publishing. Migrate in phases — start with one section, measure, then expand. Benchmark before and after — compare rankings, traffic and Core Web Vitals. Frequently asked questions Is WordPress a headless CMS? Not by default — it's a traditional CMS. But it can be used headlessly through its REST API or WPGraphQL, with a separate front end built in a framework like Next.js. Is a headless CMS more secure? Generally, yes, for the public site. Because the content backend isn't directly exposed to visitors and there's no plugin-heavy theme layer, the attack surface is smaller. You still need to secure API keys, user roles and hosting. Is headless CMS good for small businesses? Usually not as a first website. Most small businesses get better value from a traditional CMS. Headless makes sense once you need multiple channels, very high performance or custom experiences. Does a headless CMS help with AI search and chatbots? It can. Structured, well-labelled content is easier to feed into AI assistants, RAG systems and personalisation tools than page-based HTML. That said, no CMS guarantees visibility in AI search results — content quality still matters most. How long does a headless CMS project take? It depends on scope, but expect longer than a theme-based site because the front end is built from scratch. A focused marketing site can take a few weeks; a multi-channel platform can take months. Can I switch from a traditional CMS to headless later? Yes. Many teams start on WordPress and later move to headless WordPress or a dedicated headless CMS. Planning a clean content structure early makes that move much easier. Final verdict There's no universal winner in the headless CMS vs traditional CMS debate — there's only the right fit for your team, budget and growth plans. Need speed, simplicity and a low budget? Go traditional. Need omnichannel delivery, performance and design control? Go headless. Want both? Go hybrid or headless WordPress. Not sure which path fits your project? Craxinno's web development team designs and builds both — fast WordPress and Shopify sites, and custom headless builds with React and Next.js. Talk to our team and we'll help you pick the right architecture before you commit to a build.
 AWS
AWS S3 Backup Strategy: Best Practices for 2026
Quick answer: A solid AWS S3 backup strategy in 2026 has four layers. Turn on S3 Versioning with lifecycle limits. Run AWS Backup with continuous plus snapshot rules. Copy recovery points into a logically air-gapped vault in a separate account and Region. Then test restores on a schedule, because an untested backup is a guess. That's the whole strategy in one paragraph. The rest of this guide covers the decisions behind each layer, what each one costs, and the gaps AWS doesn't advertise loudly. Key takeaways S3's 11 nines of durability protects you from AWS losing your data. It does nothing when you (or an attacker with your keys) delete it. Replication is not a backup. It copies mistakes as fast as it copies good data. AWS Backup's continuous mode gives point-in-time restore for up to 35 days. Snapshots cover anything longer, up to 99 years. The low-cost warm tier (launched November 2025) cuts long-term S3 backup storage by up to 30%. Since August 2026 you can read backup data through S3 Access Points without running a full restore. That changes how cheaply you can test. Why "11 nines" isn't an S3 backup strategy Here's the conversation we keep having with founders. "We're on S3. It's 99.999999999% durable. Why would we need backups?" Then picture this. A developer runs a cleanup script against the wrong bucket on a Friday evening. Or an IAM access key leaks in a public repo, and someone encrypts or deletes every object they can reach. S3 performs those deletes with the same 11-nines reliability it uses to store your files. Durability worked perfectly. Your data is still gone. Durability is a promise about hardware. A backup is a promise about your ability to undo things . Those are different contracts, and the AWS shared responsibility model puts the second one on you. So the real question for an AWS S3 backup strategy is: what are you recovering from? Start with the threat model, not the tools Most S3 backup setups we audit were built tool-first. Someone enabled versioning, someone else added replication, and nobody wrote down what failure each piece was supposed to handle. Flip it. List the failures, then pick the control. Failure you need to survive What actually protects you What does NOT Accidental overwrite or delete of a few objects S3 Versioning Replication (it replicates the overwrite) Bad deploy corrupts thousands of objects over hours AWS Backup continuous (point-in-time restore) Versioning alone (painful to roll back at scale) Leaked credentials, ransomware, malicious insider Immutable copy in a separate account (air-gapped vault, Object Lock compliance mode) Anything in the same account the attacker controls Full Region outage Cross-Region copy or Cross-Region Replication Same-Region backups Compliance audit asking for 7-year retention AWS Backup snapshots with Vault Lock Lifecycle rules that quietly expire data Then set two numbers for each data set: RPO (Recovery Point Objective): how much data you can afford to lose. 15 minutes? A day? RTO (Recovery Time Objective): how long you can be down while restoring. Don't set one RPO for the whole company. Your user-uploaded files and your build-artifact bucket deserve very different treatment, and pricing them the same is how backup bills get out of hand. The 11 AWS S3 backup best practices for 2026 1. Tier your buckets before you back up anything Tag every bucket with a data tier. We use three: Tier 1: data the business can't run without (customer uploads, invoices, medical or financial records). Continuous backup, air-gapped copy, tight RPO. Tier 2: important but rebuildable with effort (analytics exports, processed media). Daily snapshots, cross-Region copy. Tier 3: reproducible from source (build artifacts, caches, logs you already ship elsewhere). Versioning with short retention, or no backup at all. Skipping backup for Tier 3 is a legitimate decision. Write it down so it reads as a choice, not an oversight. 2. Turn on versioning, then put a ceiling on it AWS Backup for S3 requires S3 Versioning. So does Object Lock. That makes versioning non-negotiable. But versioning without lifecycle rules is a slow cost leak. Every overwrite keeps the old copy forever. On a bucket that rewrites the same JSON file every minute, you'll pay for roughly 43,000 versions of it per month. Two lifecycle rules fix most of this: 1 2 3 4 5 6 7 8 9 10 { "Rules" : [ { "ID" : "expire-noncurrent-versions" , "Status" : "Enabled" , "Filter" : { } , "NoncurrentVersionExpiration" : { "NoncurrentDays" : 30 } , "Expiration" : { "ExpiredObjectDeleteMarker" : true } , "AbortIncompleteMultipartUpload" : { "DaysAfterInitiation" : 7 } } ] } The ExpiredObjectDeleteMarker line matters more than it looks. AWS Backup bills each delete marker as if it were a 128 KiB object, so orphaned markers on a high-churn bucket add up. Pick the NoncurrentDays value with care. Once a version expires, AWS Backup can't restore it either. Your noncurrent retention should be at least as long as your shortest RPO window. (For the exact console and CLI steps, see our AWS S3 backup setup guide .) 3. Use AWS Backup with continuous and snapshot rules together AWS Backup has two modes for S3, and the right answer for Tier 1 data is both: Continuous backup tracks changes through EventBridge and lets you restore to any point in the last 35 days . This is your "undo the bad deploy from Tuesday at 14:20" button. Snapshot (periodic) backup runs on a schedule (hourly, daily, weekly, monthly) and can be retained for up to 99 years . When both rules sit in the same backup vault, AWS Backup builds snapshots from the continuous recovery point. You get long retention without scanning the whole bucket again or paying for duplicate storage. AWS's own guidance recommends this combined setup. Two setup traps we see often: EventBridge isn't enabled on the bucket. Continuous backup silently depends on it. Check with aws s3api get-bucket-notification-configuration and look for "EventBridgeConfiguration": {} . The same bucket sits in two backup plans with continuous rules. AWS supports one continuous backup per bucket. Keep continuous and periodic recovery points in the same vault. 4. Keep one copy outside the blast radius This is the practice that separates a real AWS S3 backup strategy from a checkbox. If your backups live in the same AWS account as production, anyone with admin on that account can delete them. Ransomware crews know this. They go after the backups first. The fix in 2026 is the AWS Backup logically air-gapped vault : Recovery points are locked by default and encrypted with AWS-owned keys, or with your own KMS key since November 2025. Since November 2025 you can send primary backups directly into the air-gapped vault, so you don't pay for a second copy in a standard vault first. With multi-party approval (June 2025), a team of approvers across your AWS Organization can grant recovery access even if the source account is fully compromised or locked out. AWS added six more Regions for these vaults in July 2026, so availability is much less of a blocker than it was at launch. Our default layout: production account, a dedicated backup account in a second Region, and the air-gapped vault in that backup account. Nobody's day-to-day IAM role touches the backup account. 5. Make backups immutable on purpose You have two immutability tools, and they protect different things. S3 Object Lock works on the bucket itself. In compliance mode , no user, including the root account, can delete or shorten retention on a locked object version until the retention date passes. In governance mode , users with s3:BypassGovernanceRetention can override it. Governance mode is fine for testing. For ransomware protection, use compliance mode, and be sure about the retention period, because you can't undo it. AWS Backup Vault Lock works on recovery points in the backup vault. In compliance mode it stops anyone from deleting backups early or changing the retention policy once the cooling-off period ends. For Tier 1 data, we'd use Vault Lock (or the air-gapped vault) on the backups and save Object Lock for buckets with a regulatory write-once requirement. Object Lock on a busy production bucket can lock you into paying for data you'd love to delete. 6. Don't confuse replication with backup S3 Cross-Region Replication (CRR) is excellent at one job: keeping a live copy in another Region for failover. With S3 Replication Time Control , AWS replicates 99.99% of objects within 15 minutes. But look at what it does with bad changes: Ransomware overwrites 2 million objects with encrypted versions. CRR copies the encrypted versions. An app bug writes empty files. CRR copies the empty files. Delete marker replication is optional. Permanent deletes of specific versions are never replicated, which helps a little, but an attacker with access to both buckets doesn't care. CRR also has no built-in point-in-time restore. Rebuilding a bucket "as of last Tuesday" from replicas means stitching together S3 Inventory and Batch Operations by hand. Use CRR when your RTO is minutes and you need a hot standby. Pair it with AWS Backup for the "go back in time" requirement. One is availability, the other is recoverability, and you usually need both. 7. Assign backups by tag, so new buckets aren't forgotten The bucket that loses data is rarely the one you planned for. It's the one a developer created six months ago for "a quick feature." Assign resources to AWS Backup plans by tag (for example backup-tier = tier1 ), not by listing bucket ARNs. Then enforce the tag: Add it to your Terraform or CloudFormation bucket module so every new bucket gets one. Use AWS Backup Audit Manager or an AWS Config rule to flag buckets that have no backup tier tag. For multi-account setups, push backup policies through AWS Organizations so new accounts inherit them. 8. Cut storage costs with the warm tier and smarter retention AWS Backup storage for S3 runs about $0.05 per GB-month in US East (N. Virginia), against $0.023 for S3 Standard itself. Backups can easily cost more than the bucket they protect. A few levers: Turn on the low-cost warm tier. Launched November 2025, it moves backed-up objects that have been in the vault at least 60 days to a tier about 30% cheaper (roughly $0.035 per GB-month in AWS's example), with the same restore speed. There's a one-time fee of about $0.01 per 1,000 objects to transition. Watch small objects. Objects under 128 KB are billed as 128 KB, even in the warm tier. A bucket of millions of tiny thumbnails is a bad warm-tier candidate, and sometimes a bad AWS Backup candidate overall. Exclude ACLs and object tags if you don't need them restored. AWS Backup lets you disable both in advanced backup settings. Delete expired recovery points and partial backups. They keep billing until they're gone. AWS published a worked example worth stealing for your own business case: 500 TB and 1 billion objects in US East, 80% of objects tiered. Monthly backup storage dropped from $25,600 to $19,456. The $8,000 transition fee pays for itself in under two months. 9. Get encryption and key access right Encryption is where restores fail at 2 a.m. SSE-S3 and SSE-KMS objects back up fine. With SSE-KMS, the AWS Backup role needs kms:Decrypt on the source key, and you'll see those calls in CloudTrail. SSE-C (customer-provided keys) is not supported by AWS Backup. If any of your buckets use it, you need a different backup path for those objects. If you use a customer-managed KMS key for an air-gapped vault, protect that key's policy as carefully as the vault itself. Losing the key means losing the backup. One more trap: if CloudTrail data events or S3 server access logs are enabled for a backed-up bucket, deliver them to a different bucket. Logging into the bucket being logged creates an endless write loop, and AWS Backup will dutifully back up every log line. 10. Know what AWS Backup does NOT back up This list surprises almost every team we review: Bucket configuration: bucket policies, CORS, lifecycle rules, access points and bucket settings are not included. Restore gives you objects, not the bucket as it was. S3 Glacier Flexible Retrieval and Glacier Deep Archive objects are not supported. Directory buckets (S3 Express One Zone) and S3 on Outposts are not supported. General purpose buckets only. Restored objects don't keep their original version ID, creation date, storage class, or ETag. The answer for bucket configuration is infrastructure as code. If your buckets live in Terraform or CloudFormation, the config is "backed up" in Git. If they were clicked together in the console, fix that before you need a restore. 11. Test restores like you mean it Every backup strategy looks great until the first restore. Teams find out during the incident that the IAM role can't decrypt the KMS key, or that the restore of 40 million objects needs a service limit increase, or that the "daily" backup job failed silently three weeks ago. What changed in 2026 is how cheap testing has become: Backup access points (August 2026). AWS Backup can now create read-only S3 Access Points on a recovery point. You can run GetObject , HeadObject and ListObjectsV2 against backup data directly, with no restore job. That's perfect for spot-checking files, validating data, or forensics after an incident. The recovery point can't be deleted while an access point is active. AWS Backup restore testing runs scheduled restores into an isolated environment and records whether they worked. Amazon GuardDuty Malware Protection for AWS Backup (November 2025) scans recovery points for malware before you restore, so you don't restore the infection along with the data. A simple cadence we recommend: automated restore tests monthly for Tier 1, quarterly for Tier 2, and one full game-day restore of a Tier 1 bucket every year with a stopwatch running. Compare the result against the RTO you wrote down in step one. Sample S3 backup strategies by company stage Not everyone needs the full stack on day one. Here's how we'd scale it. Early-stage startup Growing SaaS Regulated / enterprise Versioning + lifecycle Yes Yes Yes AWS Backup Daily snapshots, 30-day retention Continuous + daily snapshots Continuous + daily/monthly snapshots, multi-year retention Separate backup account Optional Yes Yes, with multi-party approval Air-gapped vault / Vault Lock Nice to have Yes for Tier 1 Required Cross-Region Backup copy only Backup copy + CRR for Tier 1 CRR with RTC + backup copy Restore testing Quarterly manual check Monthly automated Monthly automated + annual game day + audit reports If you're still picking your stack, our SaaS tech stack guide for 2026 covers where S3 fits next to your database and hosting choices. Common S3 backup mistakes we keep finding Backups in the same account as production. The single most common gap, and the one ransomware exploits. Lifecycle rules shorter than the RPO. Old versions expire before anyone notices the corruption. No alert on failed backup jobs. Wire AWS Backup job events to EventBridge and send failures to Slack or PagerDuty. Assuming Glacier objects are covered. They aren't. Never timing a restore. Your RTO is a guess until you've measured it. These are the same kind of quiet failures we wrote about in the real cost of bad software : cheap to prevent, very expensive to discover late. Need a second pair of eyes on your S3 backups? At Craxinno we design and ship cloud infrastructure for startups and growing businesses, including AWS Backup plans, multi-account setups and restore runbooks. If you'd like us to review your current setup against the checklist above, talk to our team and we'll tell you where the gaps are.
© 2026 — Craxinno Technologies